Originally reported on November 11, 2026.
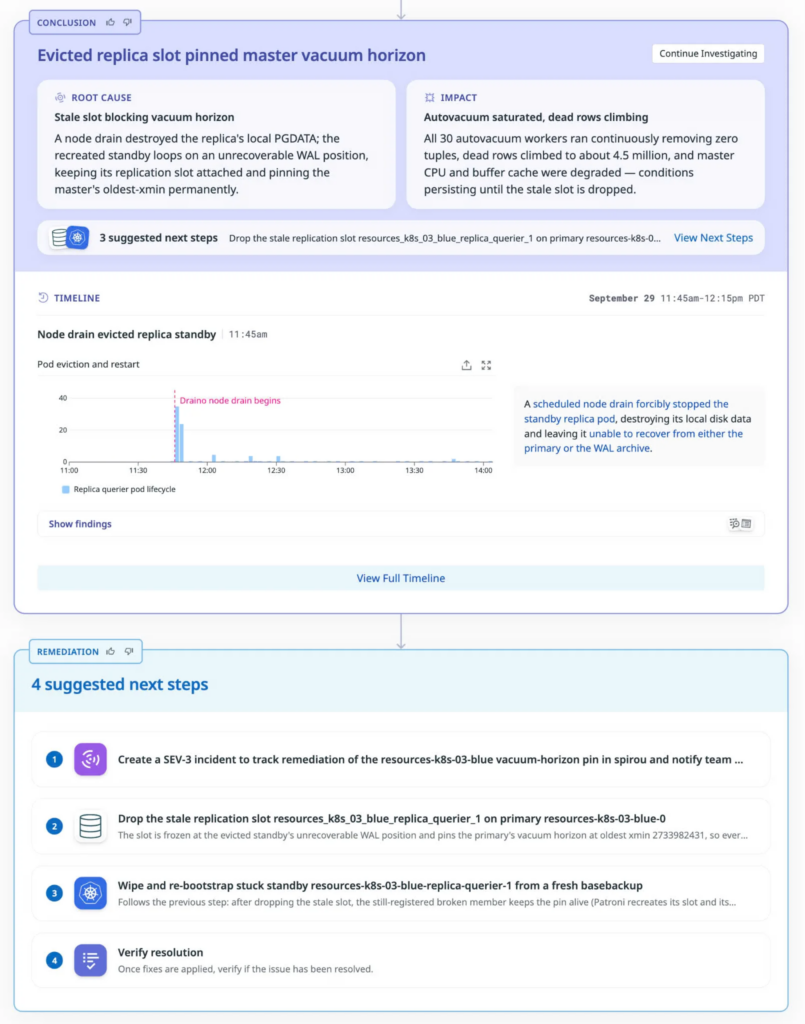
Datadog has introduced Scout, a model for investigating production incidents within its Bits Investigation AI SRE product. It can receive alerts, examine telemetry and suggest likely causes. Datadog engineers and a small number of customers are using it in a closed preview; the company has not announced a general release date.
Datadog’s aim is to make it affordable for Bits to begin investigating every alert while an engineer is still responding. An investigation can require repeated model calls to query data, assess results and decide what to inspect next. Datadog says the cost of general-purpose models has made that approach impractical at scale.
On Datadog’s AlertEval benchmark, the company reports that Scout medium performed similarly to GPT-6.1 Sol high and Claude Opus 5.5 high, at an estimated inference cost of one-third to one-eighth as much. Datadog also says Scout xhigh performed comparably to Claude Fable 5.1 xhigh at one-quarter of the cost. It has not published absolute pricing; the comparisons are relative to the cost of one Scout medium investigation.
AlertEval uses real alerts, archived telemetry and incident explanations written by Datadog engineers. An LLM judge compares model reports with expert reports, scoring matches on direct and root causes while penalizing contradictions and unsupported inferences. Datadog cautions that its 0–100 score is not the percentage of incidents successfully resolved.
Scout is built on GLM-5.3 Flash. Datadog says it used reinforcement learning on simulated incidents derived from patterns in historical cases, with alerts, queryable telemetry and known root causes. The company says the training material does not contain customer data. Its technical report also describes a change in training approach: rewarding only final conclusions initially encouraged the model to stop investigating early, so the team added rewards for exploration and supporting evidence.
In a second evaluation, conducted by Datadog on the public 90-scenario SREGym dataset, Scout resolved 71 cases at medium, 79 at high and 80 at xhigh. GPT-6.1 Sol xhigh resolved 82. Datadog ran these tests and the other model comparisons itself, so independent testing would help establish how well the results hold up. After Scout’s announcement, independent AI news account AGTP likewise noted that AlertEval had not been independently tested and called for an audit trail of evidence the model considered and discarded.
For now, Scout investigates incidents, provides a diagnosis and suggests recovery steps; engineers remain responsible for making changes. Datadog says it plans to add more failure types to its simulated training cases and ultimately wants Bits to be able to carry out remediation.